
facebook/mask2former-swin-large-cityscapes-semantic
Mask2Former Mask2Former model trained on Cityscapes semantic segmentation (large-sized version, Swin backbone). It was introduced in the paper Masked-attention Mask Transformer for Universal Image Segmentation (https://arxiv.org/abs/2112.01527) and...
Thành tựu nổi bật
Những danh hiệu mới nhất của dự án
#1 Repository Của Tháng
#1 Repository Của Tháng
#1 Repository Của Tháng
Mask2Former
Mask2Former model trained on Cityscapes semantic segmentation (large-sized version, Swin backbone). It was introduced in the paper Masked-attention Mask Transformer for Universal Image Segmentation and first released in this repository.
Disclaimer: The team releasing Mask2Former did not write a model card for this model so this model card has been written by the Hugging Face team.
Model description
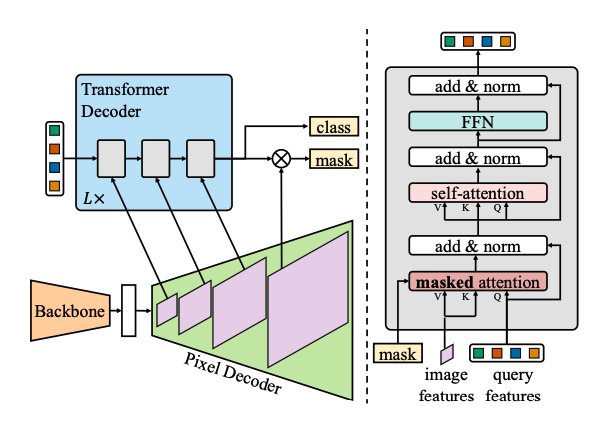
Mask2Former addresses instance, semantic and panoptic segmentation with the same paradigm: by predicting a set of masks and corresponding labels. Hence, all 3 tasks are treated as if they were instance segmentation. Mask2Former outperforms the previous SOTA, MaskFormer both in terms of performance an efficiency by (i) replacing the pixel decoder with a more advanced multi-scale deformable attention Transformer, (ii) adopting a Transformer decoder with masked attention to boost performance without without introducing additional computation and (iii) improving training efficiency by calculating the loss on subsampled points instead of whole masks.
Intended uses & limitations
You can use this particular checkpoint for panoptic segmentation. See the model hub to look for other fine-tuned versions on a task that interests you.
How to use
Here is how to use this model:
import requests
import torch
from PIL import Image
from transformers import AutoImageProcessor, Mask2FormerForUniversalSegmentation


# load Mask2Former fine-tuned on Cityscapes semantic segmentation
processor = AutoImageProcessor.from_pretrained("facebook/mask2former-swin-large-cityscapes-semantic")
model = Mask2FormerForUniversalSegmentation.from_pretrained("facebook/mask2former-swin-large-cityscapes-semantic")

url = "http://images.cocodataset.org/val2017/000000039769.jpg"
image = Image.open(requests.get(url, stream=True).raw)
inputs = processor(images=image, return_tensors="pt")

with torch.no_grad():
    outputs = model(**inputs)

# model predicts class_queries_logits of shape `(batch_size, num_queries)`
# and masks_queries_logits of shape `(batch_size, num_queries, height, width)`
class_queries_logits = outputs.class_queries_logits
masks_queries_logits = outputs.masks_queries_logits

# you can pass them to processor for postprocessing
predicted_semantic_map = processor.post_process_semantic_segmentation(outputs, target_sizes=[image.size[::-1]])[0]
# we refer to the demo notebooks for visualization (see "Resources" section in the Mask2Former docs)
For more code examples, we refer to the documentation.
Dự án tương tự
Khám phá các dự án và mô hình AI khác có sự tương đồng.
all-MiniLM-L6-v2 This is a sentence-transformers(https://www.SBERT.net) model: It maps sentences & paragraphs to a 384 dimensional dense vector space and can be used for tasks like clustering or semantic search. Usage (Sentence-Transformers) Using t...
Cross-Encoder for MS Marco This model was trained on the MS Marco Passage Ranking(https://github.com/microsoft/MSMARCO-Passage-Ranking) task. The model can be used for Information Retrieval: Given a query, encode the query will all possible passages...
Qwen3.8-27B !Note This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. !Tip F...
BRIA Background Removal v1.4 Model Card RMBG v1.4 is our state-of-the-art background removal model, designed to effectively separate foreground from background in a range of categories and image types. This model has been trained on a carefully sele...
FlagEmbedding Model List | FAQ | Usage | Evaluation | Train | Contact | Citation | License More details please refer to our Github: FlagEmbedding(https://github.com/FlagOpen/FlagEmbedding). If you are looking for a model that supports more languages,...
sentence-transformers/paraphrase-multilingual-MiniLM-L12-v2 This is a sentence-transformers(https://www.SBERT.net) model: It maps sentences & paragraphs to a 384 dimensional dense vector space and can be used for tasks like clustering or semantic se...
BERT base model (uncased) Pretrained model on English language using a masked language modeling (MLM) objective. It was introduced in this paper(https://arxiv.org/abs/1810.04805) and first released in this repository(https://github.com/google-resear...
GPT-2 Test the whole generation capabilities here: https://transformer.huggingface.co/doc/gpt2-large Pretrained model on English language using a causal language modeling (CLM) objective. It was introduced in this paper(https://d4mucfpksywv.cloudfro...
Whisper Whisper is a state-of-the-art model for automatic speech recognition (ASR) and speech translation, proposed in the paper Robust Speech Recognition via Large-Scale Weak Supervision(https://huggingface.co/papers/2212.04356) by Alec Radford et...