
shibing624/chatglm3-6b-csc-chinese-lora
Chinese Spelling Correction LoRA Model ChatGLM3-6B中文纠错LoRA模型 shibing624/chatglm3-6b-csc-chinese-lora evaluate test data: The overall performance of shibing624/chatglm3-6b-csc-chinese-lora on CSC test: |inputtext|pred| |:--- |:--- | |对下面文本纠错:少先队员因该为老...
Thành tựu nổi bật
Những danh hiệu mới nhất của dự án
#1 Repository Của Tuần
#1 Repository Của Tuần
#1 Repository Của Tuần
Chinese Spelling Correction LoRA Model
ChatGLM3-6B中文纠错LoRA模型
shibing624/chatglm3-6b-csc-chinese-lora evaluate test data:
The overall performance of shibing624/chatglm3-6b-csc-chinese-lora on CSC test:
| input_text | pred |
|---|---|
| 对下面文本纠错:少先队员因该为老人让坐。 | 少先队员应该为老人让座。 |
在CSC测试集上生成结果纠错准确率高,由于是基于THUDM/chatglm3-6b模型,结果常常能带给人惊喜,不仅能纠错,还带有句子润色和改写功能。
Usage
本项目开源在 pycorrector 项目:pycorrector,可支持ChatGLM原生模型和LoRA微调后的模型,通过如下命令调用:
Install package:
pip install -U pycorrector
from pycorrector import GptCorrector
model = GptCorrector("THUDM/chatglm3-6b", "chatglm", peft_name="shibing624/chatglm3-6b-csc-chinese-lora")
r = model.correct_batch(["少先队员因该为老人让坐。"])
print(r) # ['少先队员应该为老人让座。']
Usage (HuggingFace Transformers)
Without pycorrector, you can use the model like this:
First, you pass your input through the transformer model, then you get the generated sentence.
Install package:
pip install transformers
import os

import torch
from peft import PeftModel
from transformers import AutoTokenizer, AutoModel

os.environ["KMP_DUPLICATE_LIB_OK"] = "TRUE"
tokenizer = AutoTokenizer.from_pretrained("THUDM/chatglm3-6b", trust_remote_code=True)
model = AutoModel.from_pretrained("THUDM/chatglm3-6b", trust_remote_code=True).half().cuda()
model = PeftModel.from_pretrained(model, "shibing624/chatglm3-6b-csc-chinese-lora")

sents = ['对下面文本纠错\n\n少先队员因该为老人让坐。',
         '对下面文本纠错\n\n下个星期,我跟我朋唷打算去法国玩儿。']


def get_prompt(user_query):
    vicuna_prompt = "A chat between a curious user and an artificial intelligence assistant. " \
                    "The assistant gives helpful, detailed, and polite answers to the user's questions. " \
                    "USER: {query} ASSISTANT:"
    return vicuna_prompt.format(query=user_query)


for s in sents:
    q = get_prompt(s)
    input_ids = tokenizer(q).input_ids
    generation_kwargs = dict(max_new_tokens=128, do_sample=True, temperature=0.8)
    outputs = model.generate(input_ids=torch.as_tensor([input_ids]).to('cuda:0'), **generation_kwargs)
    output_tensor = outputs[0][len(input_ids):]
    response = tokenizer.decode(output_tensor, skip_special_tokens=True)
    print(response)
output:
少先队员应该为老人让座。
下个星期,我跟我朋友打算去法国玩儿。
模型文件组成:
chatglm3-6b-csc-chinese-lora
    ├── adapter_config.json
    └── adapter_model.bin
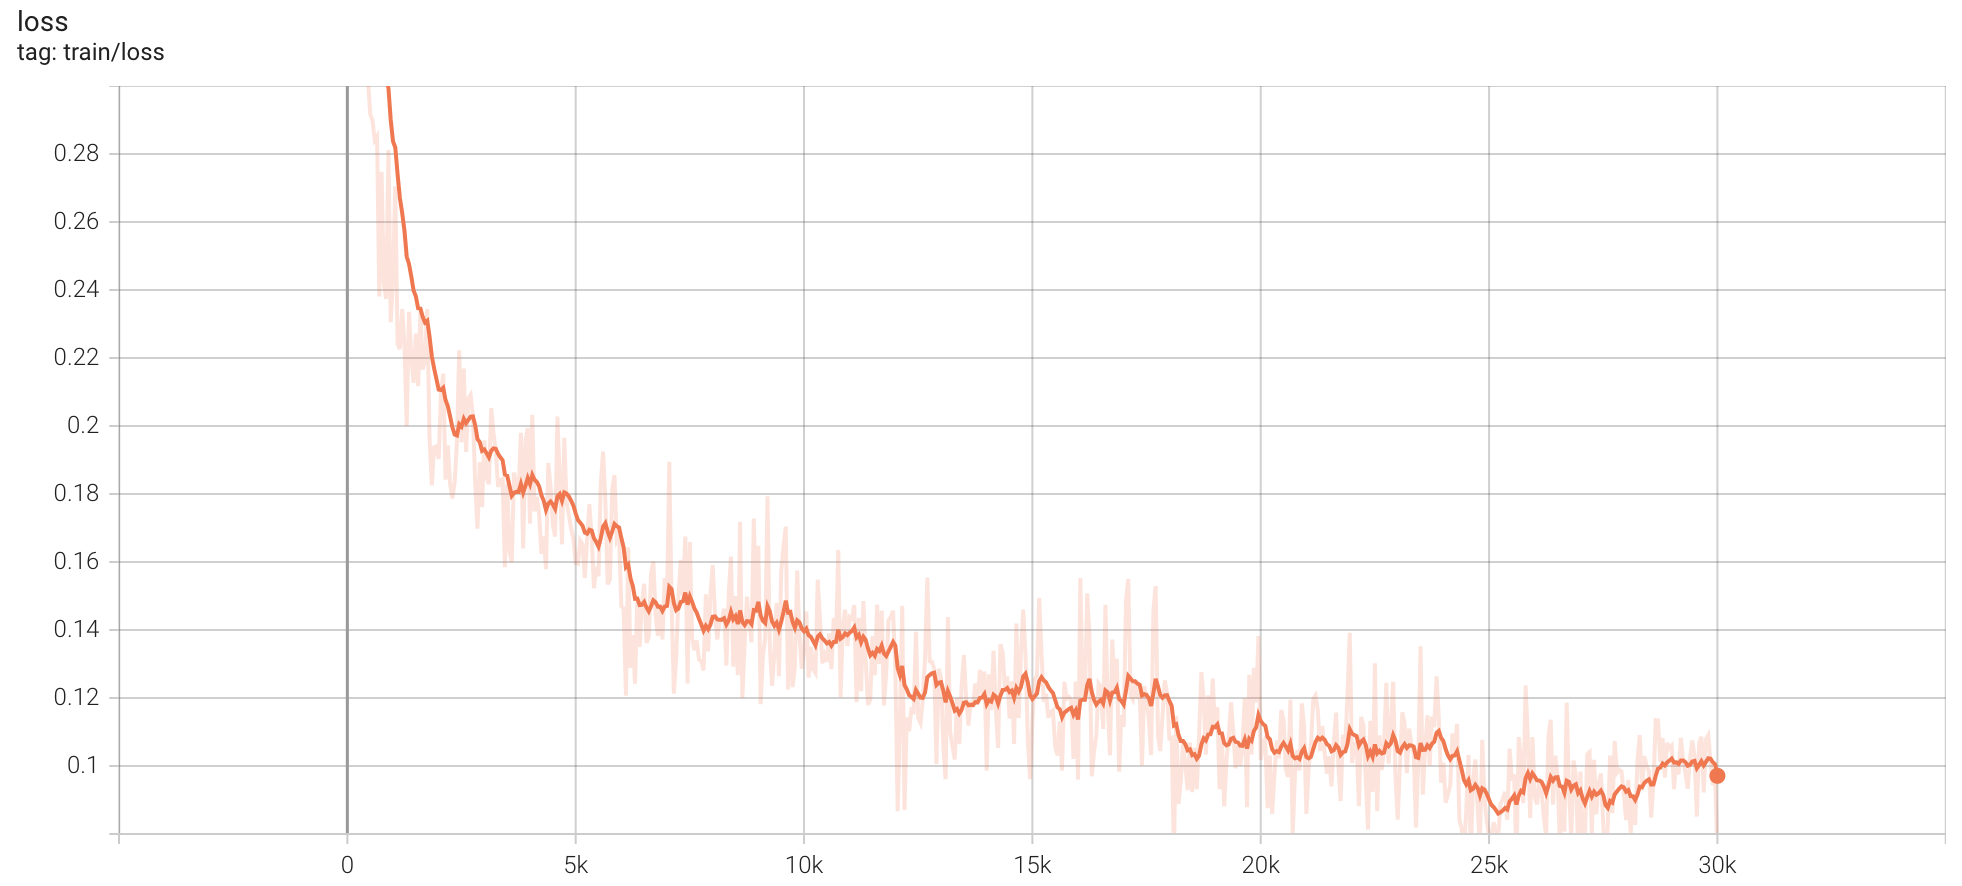
训练参数:
- num_epochs: 5
- per_device_train_batch_size: 6
- learning_rate: 2e-05
- best steps: 25100
- train_loss: 0.0834
- lr_scheduler_type: linear
- base model: THUDM/chatglm3-6b
- warmup_steps: 50
- "save_strategy": "steps"
- "save_steps": 500
- "save_total_limit": 10
- "bf16": false
- "fp16": true
- "optim": "adamw_torch"
- "ddp_find_unused_parameters": false
- "gradient_checkpointing": true
- max_seq_length: 512
- max_length: 512
- prompt_template_name: vicuna
- 6 * V100 32GB, training 48 hours
训练数据集
训练集包括以下数据:
- 中文拼写纠错数据集:https://huggingface.co/datasets/shibing624/CSC
- 中文语法纠错数据集:https://github.com/shibing624/pycorrector/tree/llm/examples/data/grammar
- 通用GPT4问答数据集:https://huggingface.co/datasets/shibing624/sharegpt_gpt4
如果需要训练文本纠错模型,请参考https://github.com/shibing624/pycorrector
Citation
@software{pycorrector,
  author = {Ming Xu},
  title = {pycorrector: Text Error Correction Tool},
  year = {2023},
  url = {https://github.com/shibing624/pycorrector},
}
Dự án tương tự
Khám phá các dự án và mô hình AI khác có sự tương đồng.
Model Information The Meta Llama 3.1 collection of multilingual large language models (LLMs) is a collection of pretrained and instruction tuned generative models in 8B, 70B and 405B sizes (text in/text out). The Llama 3.1 instruction tuned text onl...
GPT-2 Test the whole generation capabilities here: https://transformer.huggingface.co/doc/gpt2-large Pretrained model on English language using a causal language modeling (CLM) objective. It was introduced in this paper(https://d4mucfpksywv.cloudfro...
Model Details Meta developed and released the Meta Llama 3 family of large language models (LLMs), a collection of pretrained and instruction tuned generative text models in 8 and 70B sizes. The Llama 3 instruction tuned models are optimized for dia...
Qwen3-0.6B Qwen3 Highlights Qwen3 is the latest generation of large language models in Qwen series, offering a comprehensive suite of dense and mixture-of-experts (MoE) models. Built upon extensive training, Qwen3 delivers groundbreaking advancement...
Try gpt-oss · Guides · Model card · OpenAI blog Welcome to the gpt-oss series, OpenAI’s open-weight models(https://openai.com/open-models) designed for powerful reasoning, agentic tasks, and versatile developer use cases. We’re releasing two flavors...
Try gpt-oss · Guides · Model card · OpenAI blog Welcome to the gpt-oss series, OpenAI’s open-weight models(https://openai.com/open-models) designed for powerful reasoning, agentic tasks, and versatile developer use cases. We’re releasing two flavors...
Model Details Meta developed and released the Meta Llama 3 family of large language models (LLMs), a collection of pretrained and instruction tuned generative text models in 8 and 70B sizes. The Llama 3 instruction tuned models are optimized for dia...
DeepSeek-R1 Paper Link👁️ 1. Introduction We introduce our first-generation reasoning models, DeepSeek-R1-Zero and DeepSeek-R1. DeepSeek-R1-Zero, a model trained via large-scale reinforcement learning (RL) without supervised fine-tuning (SFT) as a p...
GLM-5.2 👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.2 blog and GLM-5 Technical report. 📍 Use GLM-5.2 API services on Z.ai API Platform. 🔜 Try GLM-5.2 here. Paper GitHub Introduction We're introducing GLM-5.2, our latest flagshi...