
h2oai/h2ogpt-research-oasst1-llama-65b
h2oGPT Model Card Summary H2O.ai's h2ogpt-research-oasst1-llama-65b is a 65 billion parameter instruction-following large language model (NOT licensed for commercial use). - Base model: decapoda-research/llama-65b-hf(https://huggingface.co/decapoda-...
Thành tựu nổi bật
Những danh hiệu mới nhất của dự án
#2 Repository Của Tuần
#3 Repository Của Tuần
#1 Repository Của Tuần
h2oGPT Model Card
Summary
H2O.ai's h2ogpt-research-oasst1-llama-65b is a 65 billion parameter instruction-following large language model (NOT licensed for commercial use).
- Base model: decapoda-research/llama-65b-hf
- Fine-tuning dataset: h2oai/openassistant_oasst1_h2ogpt_graded
- Data-prep and fine-tuning code: H2O.ai GitHub
- Training logs: zip
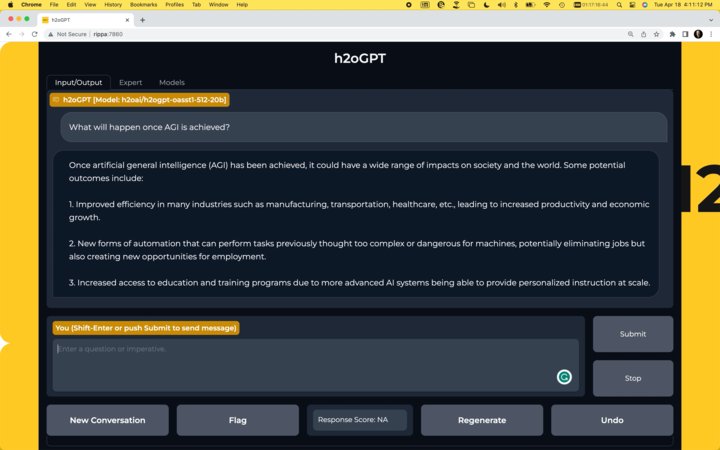
Chatbot
- Run your own chatbot: H2O.ai GitHub
Usage
To use the model with the transformers library on a machine with GPUs, first make sure you have the following libraries installed.
pip install transformers==4.29.2
pip install accelerate==0.19.0
pip install torch==2.0.1
pip install einops==0.6.1
import torch
from transformers import pipeline, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
generate_text = pipeline(model="h2oai/h2ogpt-research-oasst1-llama-65b", tokenizer=tokenizer, torch_dtype=torch.bfloat16, trust_remote_code=True, device_map="auto", prompt_type="human_bot")
res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
Alternatively, if you prefer to not use trust_remote_code=True you can download instruct_pipeline.py,
store it alongside your notebook, and construct the pipeline yourself from the loaded model and tokenizer:
import torch
from h2oai_pipeline import H2OTextGenerationPipeline
from transformers import AutoModelForCausalLM, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", padding_side="left")
model = AutoModelForCausalLM.from_pretrained("h2oai/h2ogpt-research-oasst1-llama-65b", torch_dtype=torch.bfloat16, device_map="auto")
generate_text = H2OTextGenerationPipeline(model=model, tokenizer=tokenizer, prompt_type="human_bot")

res = generate_text("Why is drinking water so healthy?", max_new_tokens=100)
print(res[0]["generated_text"])
Model Architecture
LlamaForCausalLM(
  (model): LlamaModel(
    (embed_tokens): Embedding(32000, 8192, padding_idx=31999)
    (layers): ModuleList(
      (0-79): 80 x LlamaDecoderLayer(
        (self_attn): LlamaAttention(
          (q_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (k_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (v_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (o_proj): Linear(in_features=8192, out_features=8192, bias=False)
          (rotary_emb): LlamaRotaryEmbedding()
        )
        (mlp): LlamaMLP(
          (gate_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (down_proj): Linear(in_features=22016, out_features=8192, bias=False)
          (up_proj): Linear(in_features=8192, out_features=22016, bias=False)
          (act_fn): SiLUActivation()
        )
        (input_layernorm): LlamaRMSNorm()
        (post_attention_layernorm): LlamaRMSNorm()
      )
    )
    (norm): LlamaRMSNorm()
  )
  (lm_head): Linear(in_features=8192, out_features=32000, bias=False)
)
Model Configuration
LlamaConfig {
  "_name_or_path": "h2oai/h2ogpt-research-oasst1-llama-65b",
  "architectures": [
    "LlamaForCausalLM"
  ],
  "bos_token_id": 0,
  "custom_pipelines": {
    "text-generation": {
      "impl": "h2oai_pipeline.H2OTextGenerationPipeline",
      "pt": "AutoModelForCausalLM"
    }
  },
  "eos_token_id": 1,
  "hidden_act": "silu",
  "hidden_size": 8192,
  "initializer_range": 0.02,
  "intermediate_size": 22016,
  "max_position_embeddings": 2048,
  "max_sequence_length": 2048,
  "model_type": "llama",
  "num_attention_heads": 64,
  "num_hidden_layers": 80,
  "pad_token_id": -1,
  "rms_norm_eps": 1e-05,
  "tie_word_embeddings": false,
  "torch_dtype": "float16",
  "transformers_version": "4.30.1",
  "use_cache": true,
  "vocab_size": 32000
}
Model Validation
Model validation results using EleutherAI lm-evaluation-harness.
TBD
Disclaimer
Please read this disclaimer carefully before using the large language model provided in this repository. Your use of the model signifies your agreement to the following terms and conditions.
- Biases and Offensiveness: The large language model is trained on a diverse range of internet text data, which may contain biased, racist, offensive, or otherwise inappropriate content. By using this model, you acknowledge and accept that the generated content may sometimes exhibit biases or produce content that is offensive or inappropriate. The developers of this repository do not endorse, support, or promote any such content or viewpoints.
- Limitations: The large language model is an AI-based tool and not a human. It may produce incorrect, nonsensical, or irrelevant responses. It is the user's responsibility to critically evaluate the generated content and use it at their discretion.
- Use at Your Own Risk: Users of this large language model must assume full responsibility for any consequences that may arise from their use of the tool. The developers and contributors of this repository shall not be held liable for any damages, losses, or harm resulting from the use or misuse of the provided model.
- Ethical Considerations: Users are encouraged to use the large language model responsibly and ethically. By using this model, you agree not to use it for purposes that promote hate speech, discrimination, harassment, or any form of illegal or harmful activities.
- Reporting Issues: If you encounter any biased, offensive, or otherwise inappropriate content generated by the large language model, please report it to the repository maintainers through the provided channels. Your feedback will help improve the model and mitigate potential issues.
- Changes to this Disclaimer: The developers of this repository reserve the right to modify or update this disclaimer at any time without prior notice. It is the user's responsibility to periodically review the disclaimer to stay informed about any changes.
By using the large language model provided in this repository, you agree to accept and comply with the terms and conditions outlined in this disclaimer. If you do not agree with any part of this disclaimer, you should refrain from using the model and any content generated by it.
Dự án tương tự
Khám phá các dự án và mô hình AI khác có sự tương đồng.
Model Information The Meta Llama 3.1 collection of multilingual large language models (LLMs) is a collection of pretrained and instruction tuned generative models in 8B, 70B and 405B sizes (text in/text out). The Llama 3.1 instruction tuned text onl...
Model Details Meta developed and released the Meta Llama 3 family of large language models (LLMs), a collection of pretrained and instruction tuned generative text models in 8 and 70B sizes. The Llama 3 instruction tuned models are optimized for dia...
Model Details Meta developed and released the Meta Llama 3 family of large language models (LLMs), a collection of pretrained and instruction tuned generative text models in 8 and 70B sizes. The Llama 3 instruction tuned models are optimized for dia...
GPT-2 Test the whole generation capabilities here: https://transformer.huggingface.co/doc/gpt2-large Pretrained model on English language using a causal language modeling (CLM) objective. It was introduced in this paper(https://d4mucfpksywv.cloudfro...
Llama 2 Llama 2 is a collection of pretrained and fine-tuned generative text models ranging in scale from 7 billion to 70 billion parameters. This is the repository for the 7B fine-tuned model, optimized for dialogue use cases and converted for the...
DeepSeek-R1 Paper Link👁️ 1. Introduction We introduce our first-generation reasoning models, DeepSeek-R1-Zero and DeepSeek-R1. DeepSeek-R1-Zero, a model trained via large-scale reinforcement learning (RL) without supervised fine-tuning (SFT) as a p...
Qwen3-0.6B Qwen3 Highlights Qwen3 is the latest generation of large language models in Qwen series, offering a comprehensive suite of dense and mixture-of-experts (MoE) models. Built upon extensive training, Qwen3 delivers groundbreaking advancement...
BigScience Large Open-science Open-access Multilingual Language Model Version 1.3 / 6 July 2022 Current Checkpoint: Training Iteration 95000 Link to paper: here(https://arxiv.org/abs/2211.05100) Total seen tokens: 366B --- Model Details BLOOM is an...
Model Card for Mistral-7B-v0.1 The Mistral-7B-v0.1 Large Language Model (LLM) is a pretrained generative text model with 7 billion parameters. Mistral-7B-v0.1 outperforms Llama 2 13B on all benchmarks we tested. For full details of this model please...